
SDXL Lightning API Reference
Unified REST endpoint for high-speed model inference, asynchronous background pipelines, and real-time execution status.
Bearer Token Authentication
All requests to the LumozAI API require authentication using your secret API key. Pass your key in the standard Authorization HTTP header as a Bearer token.
curl -X POST https://lumozai.com/api/v4/run \
  -H "Authorization: Bearer YOUR_API_KEY" \
  -H "Accept: application/json" \
  -d "model_id=sdxl-lightning" \
-d "prompt=A futuristic cityscape illuminated by neon bioluminescence"<?php
$apiKey = 'YOUR_API_KEY';
$curl = curl_init();
curl_setopt_array($curl, [
CURLOPT_URL => 'https://lumozai.com/api/v4/run',
CURLOPT_RETURNTRANSFER => true,
CURLOPT_POST => true,
CURLOPT_POSTFIELDS => [
'model_id' => 'sdxl-lightning',
'prompt' => 'A futuristic cityscape illuminated by neon bioluminescence'
],
CURLOPT_HTTPHEADER => [
'Accept: application/json',
'Authorization: Bearer ' . $apiKey
]
]);
$response = curl_exec($curl);
curl_close($curl);
$result = json_decode($response, true);
print_r($result);Execute SDXL Lightning Inference
Submit a synchronous or asynchronous generation job for SDXL Lightning (sdxl-lightning). Fast-running image models return the generated asset directly; longer inference pipelines return a request_id for asynchronous polling.
Request Parameters for SDXL Lightning
7 total fields| Parameter | Type | Required | Default | Description / Allowed Values |
|---|---|---|---|---|
model_id
|
string | Required | sdxl-lightning |
Unique model identifier. Must be set to
sdxl-lightning. |
prompt
|
string | Required |
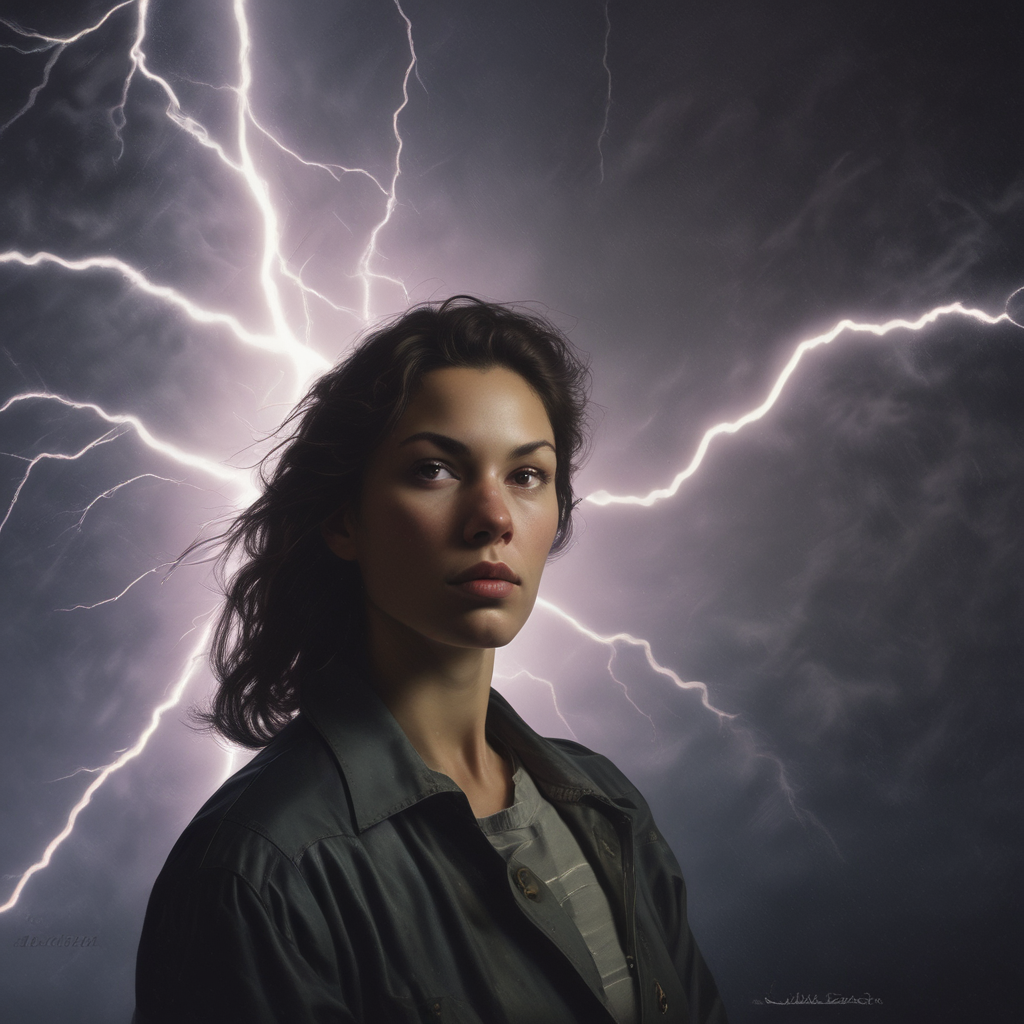
self-portrait of a woman, lightning...
|
|
negative_prompt
|
string | Optional |
worst quality, low quality
|
|
width
|
number | Optional |
1024
|
|
height
|
number | Optional |
1024
|
|
seed
|
number | Optional |
0
|
|
webhook |
string (URL) | Optional | — | Optional callback URL to receive an HTTP POST when async generation completes. |
Model-Specific Integration Code
Copy-paste production snippets configured with sdxl-lightning and tailored parameter inputs.
curl -X POST https://lumozai.com/api/v4/run \
  -H "Authorization: Bearer YOUR_API_KEY" \
  -H "Accept: application/json" \
  -d "model_id=sdxl-lightning" \
  -d "prompt=self-portrait of a woman, lightning in the background" \
  -d "negative_prompt=worst quality, low quality" \
  -d "width=1024" \
  -d "height=1024" \
-d "seed=0"import requests
url = "https://lumozai.com/api/v4/run"
headers = {
"Authorization": "Bearer YOUR_API_KEY",
"Accept": "application/json"
}
payload = {
"model_id": "sdxl-lightning",
"prompt": "self-portrait of a woman, lightning in the background",
"negative_prompt": "worst quality, low quality",
"width": 1024,
"height": 1024,
"seed": 0
}
response = requests.post(url, headers=headers, json=payload)
print(response.json())<?php
$apiKey = 'YOUR_API_KEY';
$curl = curl_init();
curl_setopt_array($curl, [
CURLOPT_URL => 'https://lumozai.com/api/v4/run',
CURLOPT_RETURNTRANSFER => true,
CURLOPT_POST => true,
CURLOPT_POSTFIELDS => [
'model_id' => 'sdxl-lightning',
'prompt' => 'self-portrait of a woman, lightning in the background',
'negative_prompt' => 'worst quality, low quality',
'width' => 1024,
'height' => 1024,
'seed' => 0
],
CURLOPT_HTTPHEADER => [
'Accept: application/json',
'Authorization: Bearer ' . $apiKey
]
]);
$response = curl_exec($curl);
curl_close($curl);
$result = json_decode($response, true);
print_r($result);const response = await fetch('https://lumozai.com/api/v4/run', {
method: 'POST',
headers: {
'Authorization': 'Bearer YOUR_API_KEY',
'Content-Type': 'application/json',
'Accept': 'application/json'
},
body: JSON.stringify({
"model_id": "sdxl-lightning",
"prompt": "self-portrait of a woman, lightning in the background",
"negative_prompt": "worst quality, low quality",
"width": 1024,
"height": 1024,
"seed": 0
})
});
const data = await response.json();
console.log(data);Response Structure (200 OK)
{
  "success": true,
  "data": {
    "request_id": 982348712938172,
    "output": "https://lumozai.com/storage/outputs/result_sdxl-lightning_9823.png",
    "output_type": "image"
  }
}Poll Asynchronous Task Status
Poll the current execution state of an asynchronous job using the returned request_id.
Request Parameters
| Parameter | Type | Required | Description |
|---|---|---|---|
request_id |
integer | Required | The unique job ID returned when calling /api/v4/run. |
{
  "success": true,
  "data": {
    "request_id": 982348712938172,
    "status": "completed",
    "output": "https://lumozai.com/storage/outputs/video_8172.mp4",
    "output_type": "video"
  }
}{
"success": true,
"data": {
"request_id": 982348712938172,
"status": "processing",
"progress": 68
}
}Standard Error Codes
The API uses conventional HTTP response codes to indicate success or failure. In general, 2xx indicates success, 4xx indicates client input issues, and 5xx indicates server errors.
| Status | Error Code | Description |
|---|---|---|
| 401 | authentication_failed |
Missing or invalid Authorization Bearer header. |
| 403 | permission_denied |
Insufficient credits or account tier permissions. |
| 404 | model_not_found |
The specified model_id does not exist or is deprecated. |
| 422 | validation_error |
Missing required parameters or invalid parameter types. |
| 429 | rate_limit_exceeded |
Request rate quota exceeded for your tier. |
| 500 | internal_server_error |
Downstream GPU compute error or worker timeout. |
{
  "success": false,
  "error": {
    "code": "validation_error",
    "message": "The model_id field is required.",
    "details": {
      "model_id": ["The model_id field is required."]
    }
  }
}Quota & Throughput Limits
Rate limits are enforced per API key to guarantee fair access and consistent low latency across GPU workers. Every API response includes informative headers:
| Header | Description |
|---|---|
X-RateLimit-Limit |
Maximum number of requests permitted per rolling hour. |
X-RateLimit-Remaining |
Number of remaining requests in the active window. |
X-RateLimit-Reset |
Unix epoch timestamp when the current window refreshes. |
X-RateLimit-Reset or implement an exponential backoff retry mechanism. Need custom enterprise rate limits? Contact our team.
Serverless Vector Memory & Semantic Search
Store, index, and retrieve vector embeddings with sub-50ms latency. Unlike traditional vector databases that charge $25 to $70 every month just to keep a cluster active, Lumoz offers zero base fees: 5,000 vector memory slots and 10,000 semantic queries per month are included free with any active balance reload.
Core Endpoints
| Method | Endpoint | Description |
|---|---|---|
| GET | /api/v1/memory/usage |
Inspect active tier, vector storage meter, and monthly search counters. |
| POST | /api/v1/memory/projects |
Create an isolated project/namespace (e.g. support-bot). |
| POST | /api/v1/memory/store |
Embed and index text documents or knowledge chunks. |
| POST | /api/v1/memory/search |
Cosine similarity search with hybrid keyword weighting. |
| DELETE | /api/v1/memory/{id} |
Delete an indexed memory item. |
Code Examples
# 1. Ingest text into an isolated namespace
curl -X POST "https://lumozai.com/api/v1/memory/store" \
  -H "Authorization: Bearer YOUR_LUMOZ_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{
    "project": "support-bot",
    "text": "Refunds are processed within 48 hours to original payment method.",
    "metadata": {"category": "billing"}
  }'

# 2. Query vector memory via cosine similarity
curl -X POST "https://lumozai.com/api/v1/memory/search" \
  -H "Authorization: Bearer YOUR_LUMOZ_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{
    "project": "support-bot",
    "query": "How long do refunds take?",
    "top_k": 3
}'import requests
headers = {
"Authorization": "Bearer YOUR_LUMOZ_API_KEY",
"Content-Type": "application/json"
}
# Store Knowledge
requests.post("https://lumozai.com/api/v1/memory/store", headers=headers, json={
"project": "support-bot",
"text": "Enterprise SLA guarantees 99.99% uptime with dedicated GPU routing.",
"metadata": {"tier": "enterprise"}
})
# Semantic Search
res = requests.post("https://lumozai.com/api/v1/memory/search", headers=headers, json={
"project": "support-bot",
"query": "What is the uptime SLA?",
"top_k": 2
})
print("Top Matches:", res.json()["results"])Zero-Code RAG with Lumoz LLM
Pass "memory": {"project": "..."} directly to /api/v1/chat/completions. Lumoz automatically pulls relevant memories into the prompt context without requiring any custom client-side vector code:
const response = await fetch("https://lumozai.com/api/v1/chat/completions", {
  method: "POST",
  headers: {
    "Authorization": "Bearer YOUR_LUMOZ_API_KEY",
    "Content-Type": "application/json"
  },
  body: JSON.stringify({
    model: "lumoz-llm-1.0",
    messages: [
      { role: "user", content: "What is your refund policy window?" }
    ],
    memory: {
      project: "support-bot",
      top_k: 3
    }
  })
});

const data = await response.json();
console.log(data.choices[0].message.content);